Prologue — The test that gates tomorrow
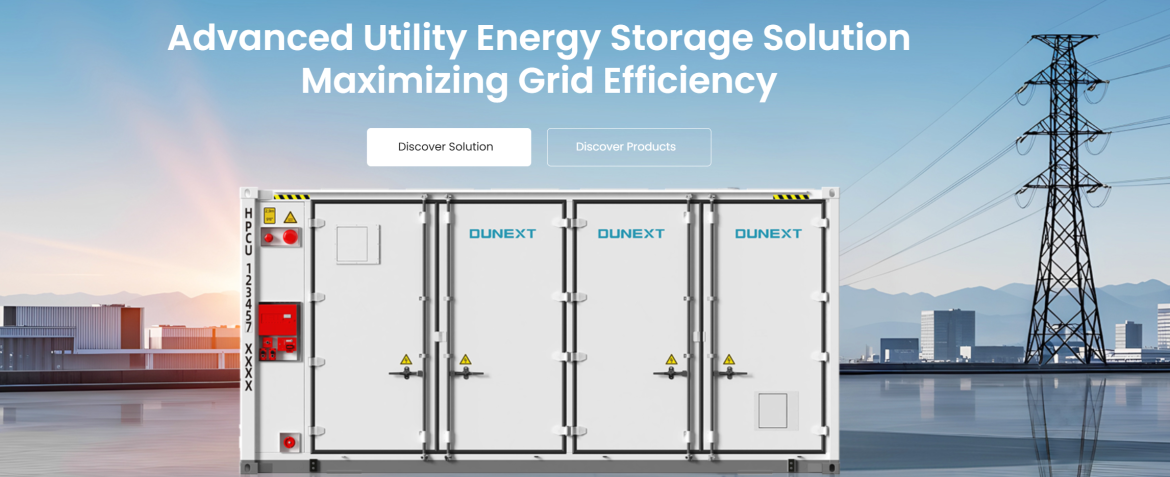
The grid of 2040 is already being designed today; prototypes that pass today’s stress suites are the only ones that survive. Imagine test rigs that simulate weeks of thermal cycling in hours and that replay geopolitical load spikes as conditional waveforms. For integrated deployments you also need systems that speak as units — which is why an all in one energy storage system must be validated not just at cell level but as a single operational organism. The Future-Speculative view asks: what failures will matter when millions of households and autonomous factories rely on a single BESS node? Answer that with rigorous, scenario-driven testing now.
Failure modes you’ll see more of — and how to test them
Expect new combinations of stresses: thermal runaway coupled with firmware drift, supply-chain-contaminant effects across hundreds of assemblies, and grid-edge micro-events that cascade. Design tests that don’t assume independence. Practical tests to run immediately:- accelerated thermal cycling with firmware-in-the-loop to watch firmware recovery and watchdog behaviors;- staged communications loss to measure safe-shutdown timelines and state-of-charge reconciliation;- supply-variation sweeps where inverter, battery management, and cooling fight for priority.One anchor from the field: the Texas February 2021 winter storm showed how simultaneous infrastructural failures turn a local fault into systemic stress. Use that lesson to craft cross-domain test scenarios.
Documentation that stays useful for decades
Paper binders won’t survive electronic audits. Create living documentation: versioned build manifests, machine-readable test results, and time-stamped firmware hashes. Each document must answer a single question: what happened, when, and who signed the result. Practical formats:- a single-line provenance record per component: manufacturer, batch, lot, test-hash;- archived test traces stored both in immutable logs and indexed time-series for quick replay;- human-readable summaries that hide complexity but link to raw telemetry.This documentation needs to be discoverable by field technicians in adverse conditions, not just by engineers at headquarters.
Traceability: map a cell to the cloud
Traceability isn’t only about recall. It’s about targeted remediation. Link every cell, module, and controller to a persistent identity and to its complete lifecycle record. Actions to implement now:- unique, tamper-evident identifiers burned into component records at manufacture;- automated cross-references between physical identifiers and software images;- an audit layer that ties test results, installation logs, and maintenance actions into one searchable thread.Keep traces short and precise. Long, vague histories are useless when you need to decide whether to replace a module mid-deployment.
Common traps that still catch teams
Teams underestimate integration risks. Typical mistakes:- testing subsystems in isolation and assuming behaviour scales linearly;- storing documentation in disparate formats that can’t be reconciled automatically;- trusting a single vendor-supplied test report without independent replication.Avoid these by forcing cross-team test sessions, adopting one canonical provenance format, and requiring at least two independent validation passes before accepting a component for field use.
Alternatives, trade-offs, and the path forward
Should you choose modular stacks or fully integrated units? Both choices have merits. Modular systems let you swap failing elements quickly but demand stronger orchestration software. Fully integrated systems simplify deployment and are easier to test as a unit, but a single design flaw can scale wider. Evaluate on three axes:- reparability: how fast can a field crew isolate and replace a failed part;- observability: how much diagnostic data does the system expose under failure;- lifecycle traceability: how clearly can you follow a component from manufacturer to retirement.Design your testing and documentation strategy to match the chosen architecture, not the other way around.
Implementation checklist for resilient BESS production
Work through this list before field rollout:- mandate combined stress tests with real firmware and production energization;- unify documentation formats and deploy immutable logs for test results;- assign a tracing owner who maintains the component-to-cloud mapping;- schedule independent replication of critical tests;- run field drills that simulate compound failures and record response metrics.Simple. Brutally practical. Repeat until the system behaves predictably.
Epilogue — Where testing, records, and trace converge
Predictive scenarios show what will break; rigorous testing proves what won’t. When traceability ties every cell to a verifiable history and documentation is typed, timestamped, and tamper-resistant, you get decisions you can act on in minutes. That’s the value a compact, verifiable system brings to future grids—real resilience, not promises. The friction between design ambition and operational reality gets resolved through transparent records and reproducible tests, the very foundation that makes the integrated systems of tomorrow reliable and manageable, as seen through the lens of Dunext.